An Empirical 8-Model Benchmark on Agent Harness Architecture, Model Over-Refusal, Token Efficiency, and Enterprise Sovereignty in Modern AI-Driven Penetration Testing
1. The Core Thesis: Offensive Capability Is a Function of the Harness, Not the Raw Model
In my book on Harness Engineering, I laid out how to build a secure and long-horizon agent to extend a frontier model’s capability. The book’s central thesis also applies to agent-based red teaming systems: an autonomous AI agent’s offensive, penetration testing, and red-teaming capability depends primarily on its orchestration harness, state-machine memory, and deterministic tool execution environment—not solely on the raw parameter scale or public benchmark leaderboard ranking of its underlying Large Language Model (LLM).
While the broader AI ecosystem remains transfixed by raw model metrics (MMLU, SWE-bench, GSM8K, and Chatbot Arena rankings), offensive cybersecurity operates under an entirely distinct set of constraints. Offensive security is not a single-shot autocomplete task. It is a highly interactive, stateful, adversarial feedback loop requiring rigorous reconnaissance, dynamic hypothesis testing, payload syntax adaptation, multi-hop pivoting, and evidence-backed proof-of-concept (PoC) validation.
When organizations connect a bleeding-edge frontier LLM directly to a standard ReAct or generic agentic loop and instruct it to ‘penetration test this enterprise target,’ the result is almost invariably failure: catastrophic context window bloat, hallucinated CVE vulnerability claims, broken shell interactions, and endless repetitive retry loops.
📌 THE HARNESS PRINCIPLE
Raw frontier model intelligence without an offensive harness is like a Formula 1 engine dropped into a chassis with no steering rack, transmission, or brakes. In offensive security, the harness provides the state memory, tool sandboxing, anti-hallucination gates, and attack-graph reasoning that turn raw model inference into verified exploits.
2. The Alignment Paradox: Why Heavily Aligned Frontier Models Stumble on Red Teaming
Recent empirical research and benchmarking from Ridge Security (ridgesecurity.ai), creators of the RidgeGen agentic framework and RidgeBot platform, has provided compelling quantitative validation for this thesis. Their research illuminates an acute industry bottleneck: model alignment fine-tuning.
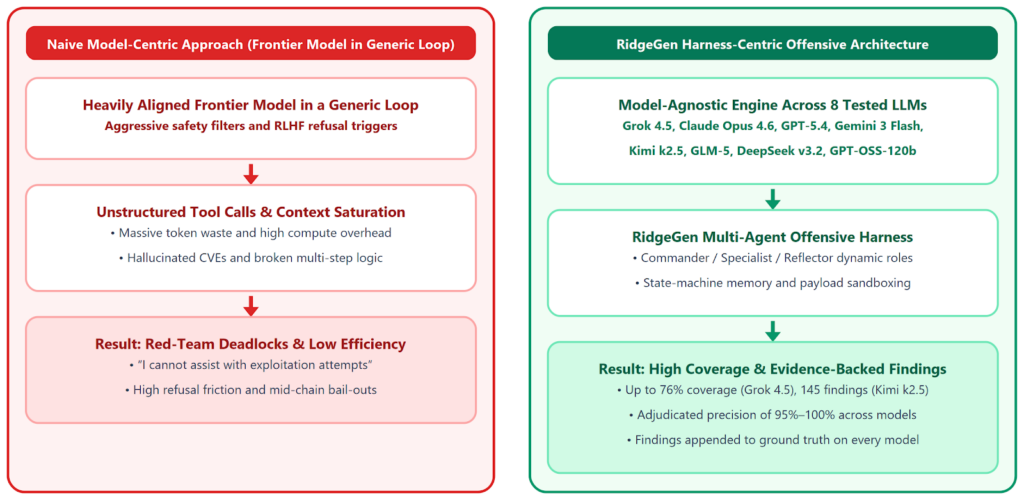
As foundation model providers race to satisfy consumer and enterprise safety mandates, latest-generation frontier models undergo aggressive alignment training: Reinforcement Learning from Human Feedback (RLHF), Direct Preference Optimization (DPO), Constitutional AI rule-sets, and internal refusal steering classifiers. While essential for preventing malicious abuse by lay users, these heavy alignment guardrails create an acute ‘Over-Refusal Tax’ during authorized, defensive security research.
When tasked with multi-step offensive operations—such as weaponizing an authorization bypass, generating proof-of-concept SQL injection payloads, constructing memory corruption exploits, or automating lateral movement—heavily aligned models frequently trigger false-positive refusal filters. The model abruptly halts execution with generic refusals: ‘I cannot generate payloads or assist with unauthorized system testing.’
Key Challenges from Over-Refusal:
1- Catastrophic Mid-Flight Bailouts: Broken Attack Chains: An autonomous attack chain often requires 15 to 30 sequential, stateful actions. If a frontier model over-refuses on Step 12 (e.g., crafting a bypass token), the entire autonomous campaign collapses.
2- Hallucinated Exploitation: When models are steered away from offensive keywords, they often invent theoretical, non-reproducible vulnerabilities or claim a vulnerability exists without validating it against the live target.
3- Exponential Token Waste: Generic agent harnesses attempt to bypass refusals with repetitive re-prompting or jailbreak heuristics, consuming millions of prompt tokens with zero confirmed exploits.
3. The Goldilocks Zone: Balancing Frontier Scale with ‘Good Enough’ Models and Elite Harnesses
The findings from Ridge Security highlight the necessity of identifying the ‘Goldilocks Zone’ in autonomous offensive AI. The prevailing enterprise temptation has been to simply point the newest, most expensive frontier API at target infrastructure and assume higher benchmark scores translate to superior red-teaming yield.
In practice, security capability follows a non-linear frontier:
- Frontier API (Raw / Unharnessed): High latency, severe alignment over-refusals, high compute overhead, and potential data leakage across third-party API boundaries.
- Open-Source LLM (Unharnessed / Basic): Low refusal rates, but easily derailed by context saturation, loses state across deep multi-hop pivots, and generates unvalidated script output.
- The RidgeGen Sweet Spot (Any Capable Model + Specialized Harness): Model-agnostic reasoning orchestrated through dynamic Commander/Specialist roles, deterministic state tracking, sandboxed payload execution, and evidence-backed PoC verifiers that require a reproducible artifact before a finding is recorded.
Ridge Security demonstrated that when paired with a purpose-built offensive harness, a ‘good enough’ open-weights reasoning model (such as DeepSeek v3.2, GPT-OSS-120b, or GLM-5) consistently matches or outperforms raw frontier models in discovered exploit depth, completion rate, operational efficiency, and reproducibility.
4. Ridge Security’s Empirical Findings: 8-Model Benchmark on Coverage, Cost, and Token Efficiency
To rigorously evaluate model behavior under real-world penetration testing conditions, the Ridge Security research team executed a comprehensive benchmark across eight leading foundation and open-source models using the RidgeGen offensive harness. The evaluation encompassed 12 full runs per model (12/12) across 4 target host, web and API enterprise systems (see the details about the test targets in section 8.3): (4/4).
Figure 2 reports cumulative ground-truth coverage for every model against every target, pooling the three repeat runs in each cell. Read across a row to see how one model copes with different attack surfaces, and down a column to see which targets resist all of them: VAmPI falls readily to most models, while Metasploitable3 and Juice Shop hold out even against the strongest.
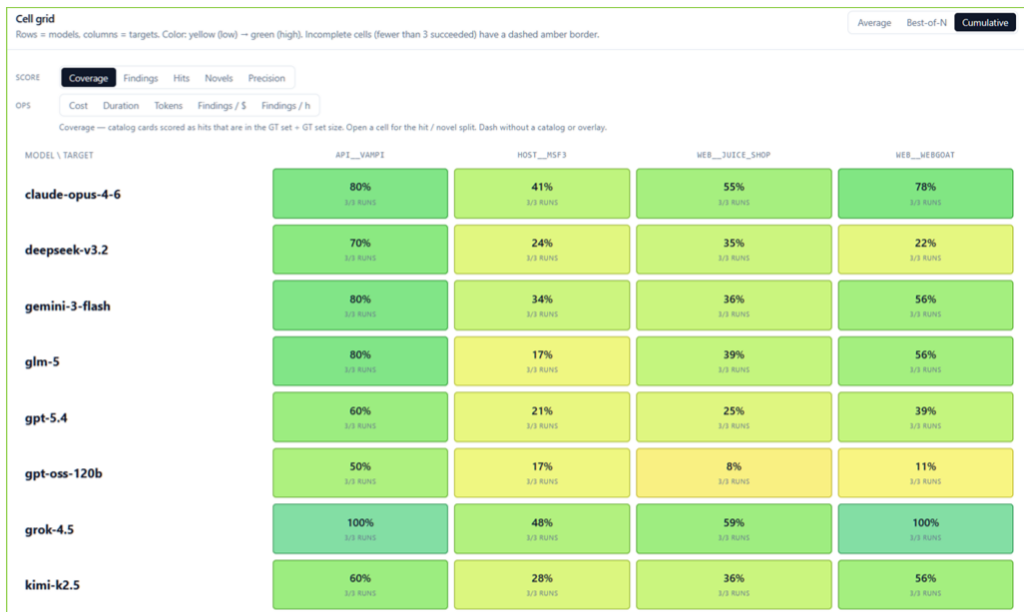
Figure 3 gives the average US dollar cost of a single successful run in each cell, and it is the sharpest divider in the benchmark. Claude Opus 4.6 costs one to two orders of magnitude more per run than the open-weights tier, and the gap widens on the two web targets, where longer agent trajectories multiply the per-token premium. (Note on open-weights hosting costs: The dollar costs reported for open-weights models such as GPT-OSS-120b and DeepSeek v3.2 reflect managed cloud API invocation rates—via AWS Bedrock and native provider endpoints—used to establish standardized enterprise telemetry and billing in this benchmark. When self-hosted by an enterprise on private VPC or on-premises infrastructure, marginal inference API costs are zero.)
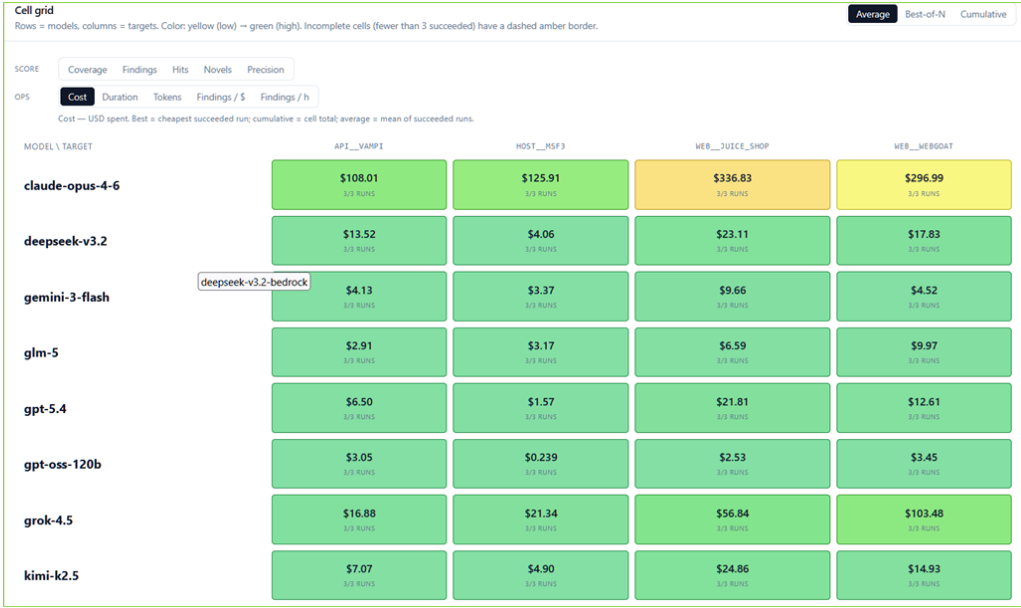
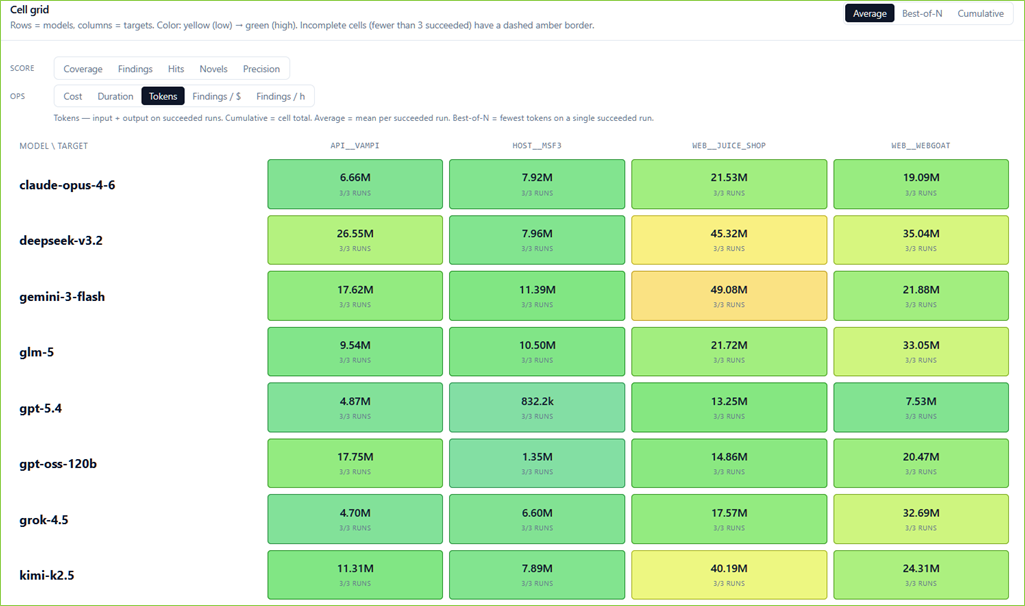
Figure 4 shows average token consumption per succeeded run. Token volume and cost do not track each other: gpt-oss-120b and DeepSeek v3.2 burn heavy token counts cheaply, while Claude Opus 4.6 spends comparatively few tokens at a high unit price. Reading Figures 3 and 4 together separates how verbose a model is from how much it charges.
Key Insights from the 8-Model Benchmark
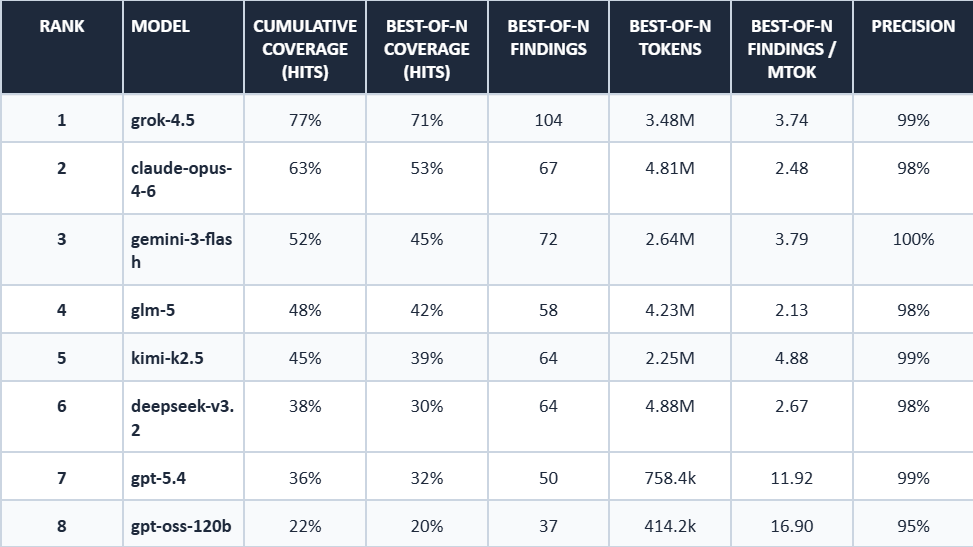
- Grok 4.5 Coverage Leadership: grok-4.5 led all models with 71% peak Best-of-N coverage (104 Best-of-N findings across 3.48M tokens) and 77% cumulative coverage, achieving a standout token efficiency of 3.74 findings per million tokens.
- Kimi k2.5 Execution Velocity: kimi-k2.5 demonstrated high token velocity in the open-weights tier, securing 64 Best-of-N findings across 2.25M tokens for 4.88 findings per million tokens (39% peak Best-of-N coverage and 45% cumulative coverage).
- Frontier Model Compute Overhead: claude-opus-4-6 achieved 53% peak Best-of-N coverage (67 Best-of-N findings across 4.81M tokens, 2.48 findings/MTOK) and 63% cumulative coverage, but required heavy compute overhead and experienced notable alignment refusal friction.
- High Efficiency on Fast & Sovereign Models: Lightweight and compact models delivered exceptional single-run token economy: gemini-3-flash captured 72 Best-of-N findings across 2.64M tokens (3.79 findings/MTOK, 45% peak / 52% cumulative coverage), while gpt-5.4 (50 Best-of-N findings on 758.4k tokens, 11.92 findings/MTOK) and gpt-oss-120b (37 Best-of-N findings on 414.2k tokens, 16.90 findings/MTOK) established the highest token finding efficiencies in the benchmark.
Total Yield Breakdown: Matched Findings and Newly Appended Findings
Ridge Security maintains a single ground-truth vulnerability list per target. Each run either matches an entry already on that list or appends a new one, so Total Yield is simply matched findings plus newly appended findings. Newly appended means only that the issue was not already on the list. All four targets are well-known public training ranges, so an appended finding is typically a minor or lower-severity issue rather than a zero-day.
Across all eight models, the RidgeGen harness consistently appended findings beyond the entries already held on each target ground-truth list:
- grok-4.5: 194 Total Yield (highest of any model, alongside 77% cumulative coverage)
- deepseek-v3.2: 162 Total Yield (highest ratio of newly appended to matched findings among all models tested)
- gemini-3-flash: 133 Total Yield (Fast, highly consistent exploit execution)
- glm-5: 127 Total Yield (balanced mix of matched and newly appended findings)
- claude-opus-4-6: 127 Total Yield (high-precision matches with a moderate append rate)
- kimi-k2.5: 120 Total Yield (steady matching with a reliable append rate)
- gpt-5.4: 107 Total Yield (slightly more newly appended findings than matched findings, with 42 matched ground-truth hits and 65 newly appended findings)
- gpt-oss-120b: 75 Total Yield (verified appended findings even on an open-weights baseline)
📌 THE APPEND PRINCIPLE
Finding issues that are not already catalogued is not reserved for proprietary frontier models. When powered by RidgeGen’s structured harness, open-source and sovereign models like DeepSeek v3.2 and GPT-OSS-120b reliably append new entries to a target ground-truth list, including business-logic flaws and non-CVE attack paths.

5. The Enterprise Sovereignty Mandate: Choose Your Own Models
While consumer AI applications thrive on hosted frontier APIs, enterprise security teams operate under strict regulatory, confidentiality, and data sovereignty mandates. Sending live vulnerability telemetry, internal IP addresses, and Active Directory schema is often an absolute non-starter for CISOs in banking, healthcare, defense, and critical infrastructure.
RidgeGen allows enterprises to use their own API keys with trusted frontier models, or they can choose self-hosted, open-weight models deployed in their VPC or on-premises. Either way, customers have control over data sovereignty in a way they’re comfortable with.
1- Total Data Sovereignty: Zero sensitive target data, exploit payloads, or vulnerability findings leave the customer’s trusted boundary; no sensitive data shared with LLMs.
2- Uninhibited Defensive Red Teaming: Open-weights models running within private enterprise infrastructure (such as DeepSeek v3.2 and GPT-OSS-120b) do not inject arbitrary external safety filters that break authorized security validation workflows.
3- Deterministic Performance & Operational Control: By combining proprietary knowledge base and toolsets, and verification processes for each finding, RidgeGen helps enterprises achieve sovereign, continuous security validation at predictable, stable scale.
6. Benchmark Methodology & Testbed Architecture: GCP Clean-Room Hosting and Mixed Model Routing
To ensure unassailable benchmark integrity, the Ridge Security engineering and research team designed a multi-cloud, clean-room testing environment:
Clean-Room Cloud Architecture
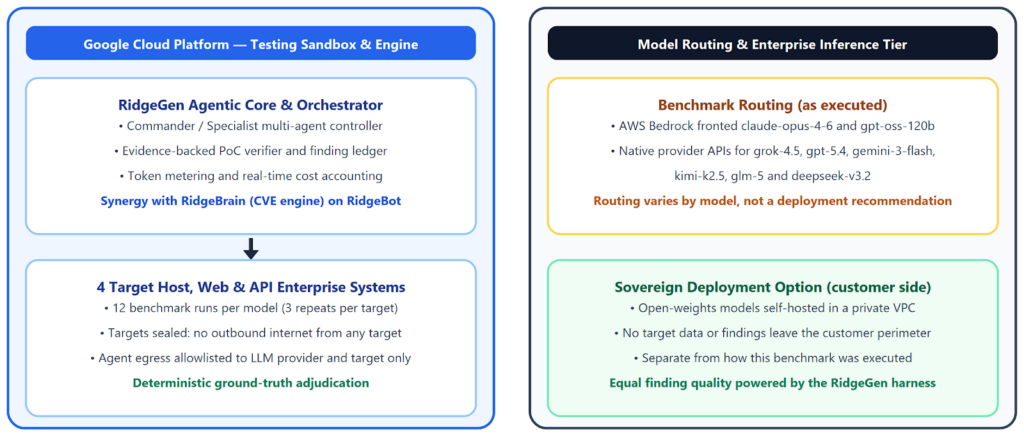
- GCP Cloud Hosting Sandbox: The core RidgeGen platform, along with target enterprise testing ranges (4 target host, web and API enterprise applications across 12 full runs per model), were hosted in isolated containerized sandboxes on Google Cloud Platform (GCP).
- Mixed Model Routing: Model access was not uniform across the benchmark. AWS Bedrock fronted Claude Opus 4.6 and GPT-OSS-120b, supplying enterprise-grade zero-data-retention guarantees, standardized telemetry, and rate-limit controls. The remaining six models (Grok 4.5, GPT-5.4, Gemini 3 Flash, Kimi k2.5, GLM-5, and DeepSeek v3.2) were reached over their native provider APIs. Routing is therefore a property of this benchmark harness rather than a recommended enterprise topology; the sovereign deployment pattern described in Section 5 is a separate customer choice.
- Rigorous Anti-Cheat Controls: Every target ran inside an isolated container with no outbound internet connectivity. The agent side necessarily reaches external LLM endpoints, and does so through a controlled proxy whose egress allowlist admits only the model provider and the target under test. The agent could therefore not query public search engines, look up pre-existing CVE write-ups, or access benchmark answer sheets, while the targets themselves stayed sealed.
7. Strategic Recommendations for CISOs and Red Team Leaders
As enterprise security organizations transition from manual penetration testing and static vulnerability scanning to continuous, autonomous threat exposure management (CTEM), Ridge Security’s research offers critical strategic guidance:
- Prioritize Harness Architecture Over Model Hype: Stop evaluating red-teaming AI tools based on which frontier LLM API they integrate with. Instead, evaluate the agent’s harness architecture: does it have state memory, dynamic multi-agent delegation, and deterministic PoC execution sandboxing?
- Require Evidence-Backed Findings, Not Assertions: Demand verifiable token-per-finding, cost-per-finding, and completion rate metrics on standard benchmark suites. Require that every reported vulnerability ship with a working, reproducible PoC, and ask vendors to publish measured precision rather than accept a blanket zero-false-positive claim. Adjudicated precision in this benchmark ranged from 95% to 100% depending on the model.
- Build for Sovereignty and Compliance: Invest in architectures that support local, private VPC, or sovereign open-source model execution to protect sensitive infrastructure data while avoiding third-party alignment refusal barriers.
- Adopt the Dual-Engine Synergy: Deploy automated engines (like RidgeBrain) for continuous, high-speed CVE hygiene, and deploy agentic AI (like RidgeGen) for deep, multi-step business logic reasoning and non-CVE attack path discovery.
Autonomous offensive security has officially moved past the prompt-engineering era. The future belongs to purpose-built, harness-driven agentic architectures that deliver verifiable, safe, and continuous security validation at enterprise scale.
8. Appendix: Evaluating Autonomous Offensive Capability: Cumulative, Best-of-N, and Average Metrics
8.1 Methodological Framework: Tri-Metric Capability Evaluation
To accurately evaluate large language models operating inside agentic offensive harnesses, benchmarking methodologies must differentiate between exploratory breadth, operational repeatability, and peak reasoning capabilities:
Best-of-N (Peak Reasoning & Token Efficiency Ceiling): Represents the single highest-performing and most token-efficient successful run in a given test cell. A weak or failed repeat run does not lower this score.
Offensive Security Value: This is the primary indicator of peak autonomous offensive capability and single-run token efficiency. Because repeat runs on a target triple token expenditure (~3× for 3 runs) while discovering mostly overlapping vulnerabilities rather than scaling linearly, dividing cumulative findings by cumulative tokens artificially penalizes repeat exploration. Best-of-N reveals the true token efficiency (Findings / MToken) of a model and harness on a single coherent run without multi-run dilution.
Average (Baseline Operational Reliability): The arithmetic mean of all succeeded runs within the test cell.
Offensive Security Value: Measures reproducibility and day-to-day dependability. High Best-of-N paired with a low Average indicates an agent that occasionally hits an exploit by chance, whereas a tight delta confirms repeatable operational capability for single-run enterprise penetration tests.
Cumulative (Exhaustive Attack Surface Yield): The deduplicated set union across all repeat runs (e.g., 3 repeats per target) divided by the Ground Truth (GT) set size, alongside total cumulative token expenditure and duration.
Offensive Security Value: Measures total exploitation yield under repeat compute. Because autonomous agents take divergent reasoning paths across runs, cumulative coverage demonstrates the true boundary of what a multi-run harness can discover across an enterprise target’s entire attack surface.
Worked example (grok-4.5). Across its 3 repeat runs the harness matched 100% of the 10-entry ground-truth list on VAmPI, 48% of 29 entries on Metasploitable3, 59% of 75 on Juice Shop, and 100% of 18 on WebGoat. Cumulative coverage is the mean of those four figures: (100 + 48 + 59 + 100) / 4 = 76.75% (reported as 77%).
Because that mean weights every target equally, VAmPI counts as much as Juice Shop despite holding seven and a half times less ground truth; weighting by ground-truth set size instead would place the same runs at 65%.
Total Cumulative Findings (134) counts every deduplicated adjudicated finding across the 12 runs. Total Yield (194) adds findings newly appended to the ground-truth lists to those that matched entries already on them.
For Token Efficiency (Findings / MToken), rather than using cumulative findings divided by 3× cumulative token spend (134 / 184.69M = 0.73, which penalizes repeat exploratory runs), the benchmark uses the Best-of-N peak token efficiency: the single most token-efficient succeeded run achieved 3.74 findings per million tokens (on host__msf3 with 13 findings on 3.48M tokens).
8.2 Empirical 8-Model Benchmark Ranking (RidgeGen Testbed)
Evaluated across 96 succeeded runs (12 runs per model across 4 enterprise target systems: VAmPI API, Metasploitable3 Host, OWASP Juice Shop, and OWASP WebGoat; 3 repeat runs per target). HITS is defined as a finding that matches the ground truth published by the application publisher. Cumulative Coverage is the mean of the four per-target cumulative coverage figures, so each target contributes equally regardless of the size of its ground-truth set. Cost and Tokens represent average consumption per run, while Finding/MToken captures peak single-run token efficiency under the Best-of-N methodology.
8.3 Granular Target Application Breakdown & Attack Surface Dimensions
The 96 benchmark runs were conducted across four enterprise target environments, each testing distinct vulnerability surfaces:
- api__vampi (REST API · 10 Ground Truth Vulnerabilities): Evaluates OWASP API Security Top 10 vulnerabilities including Broken Object Level Authorization (BOLA), mass assignment, SQL injection, and authentication token bypasses.
- host__msf3 (Metasploitable3 Linux Host · 29 Ground Truth Vulnerabilities): Evaluates operating system service enumeration, privilege escalation, SSH/FTP credential stuffing, and multi-stage lateral exploitation across network daemons.
- web__juice_shop (OWASP Juice Shop Web App · 75 Ground Truth Vulnerabilities): Evaluates modern rich client-side single-page applications (SPA) containing complex business-logic flaws, JWT manipulation, client-side validation bypass, and multi-step injection.
- web__webgoat (OWASP WebGoat Web App · 18 Ground Truth Vulnerabilities): Evaluates enterprise Java application vulnerabilities including Server-Side Request Forgery (SSRF), Java insecure deserialization, SQL injection, and cryptographical weaknesses.
8.4 Key Architectural & Capability Insights
- Frontier Capability Leader: grok-4.5 established the highest benchmark ceiling across all targets, reaching 100% cumulative coverage on both VAmPI and WebGoat, 77% cumulative coverage overall, an average run cost of $49.63 (roughly $596 across all 12 runs), and a peak Best-of-N token efficiency of 3.74 findings/Mtok (0.73 cumulative findings/Mtok across its full 184.69M tokens).
- Frontier Reliability vs. Token Overhead: claude-opus-4-6 maintained the second-highest cumulative coverage (63%) and peak Best-of-N coverage (53%), but required substantial token expenditure (13.80M tokens on average per run, 165.62M cumulative) with a Best-of-N token efficiency of 2.48 findings/Mtok (0.66 cumulative Mtok), and by far the highest spend in the benchmark at $216.94 average per run (roughly $2,603 across 12 runs, or close to $24 per finding).
- Efficiency & Sovereign Mid-Tier: gemini-3-flash (45% peak coverage, 52% cumulative coverage, 3.79 Best-of-N findings/Mtok, $5.42 average cost per run) and glm-5 (42% peak coverage, 48% cumulative coverage, 2.13 Best-of-N findings/Mtok, $5.66 average cost per run) demonstrated that lightweight models paired with structured offensive harnesses out-execute heavier unharnessed setups while maintaining high execution speed and low token overhead. Both are also among the cheapest models tested, at roughly $65 and $68 respectively across all 12 runs.
- Sovereign Append Rate: deepseek-v3.2 appended 112 findings that were not already on the ground-truth lists (162 total yield, 38% cumulative coverage, 2.67 Best-of-N findings/Mtok, $14.63 average cost per run) and kimi-k2.5 produced 145 cumulative findings (45% cumulative coverage, 4.88 Best-of-N findings/Mtok, $12.94 average cost per run), showing that open-weights and sovereign models explore attack surface broadly when guided by evidence-backed PoC verification.
- Low-Compute Baseline: gpt-oss-120b achieved 20% peak coverage (22% cumulative coverage) and 60 cumulative findings, while achieving an exceptional peak Best-of-N token efficiency of 16.90 findings/Mtok on its leanest runs (414.2k tokens), providing the cheapest baseline in the benchmark at $2.32 average cost per run (roughly $28 across all 12 runs), well suited to continuous hygiene scanning.
- Frontier Efficiency Outlier: gpt-5.4 reached 36% cumulative coverage (32% peak Best-of-N coverage) on 6.62M average tokens per run (79.46M cumulative tokens) and $10.62 average cost per run (roughly $127.50 across all 12 runs), delivering the lowest token consumption and a standout peak Best-of-N token efficiency of 11.92 findings/Mtok (on 758.4k tokens). It rivals deepseek-v3.2 on cumulative coverage (36% vs. 38%) at less than a quarter of the total token spend (79.46M vs. 344.60M tokens), demonstrating that newer frontier architectures can achieve exceptional token economy.
📌 THE MULTI-RUN COMPUTE PARADOX
In autonomous offensive security, 3 repeat runs of a lightweight or sovereign model (such as Gemini 3 Flash or GLM-5) achieve equivalent or higher cumulative ground-truth coverage (52% and 48%) than a single run of a heavy frontier model like Claude Opus 4.6 (46% average single-run coverage) while consuming comparable or lower cumulative token budgets. The cost gap is starker still: three full sweeps of Gemini 3 Flash cost roughly $65 against roughly $2,603 for Claude Opus 4.6, a ratio near 40 to 1 for 6 additional percentage points of cumulative coverage over Claude Opus (or 11 percentage points over Claude’s average single run). Multi-run exploration across stochastic reasoning paths systematically outperforms brute-force single-run frontier execution.